AI animation & restyling
Vimi
Drive a character image with motion, audio, or text references.
What it does
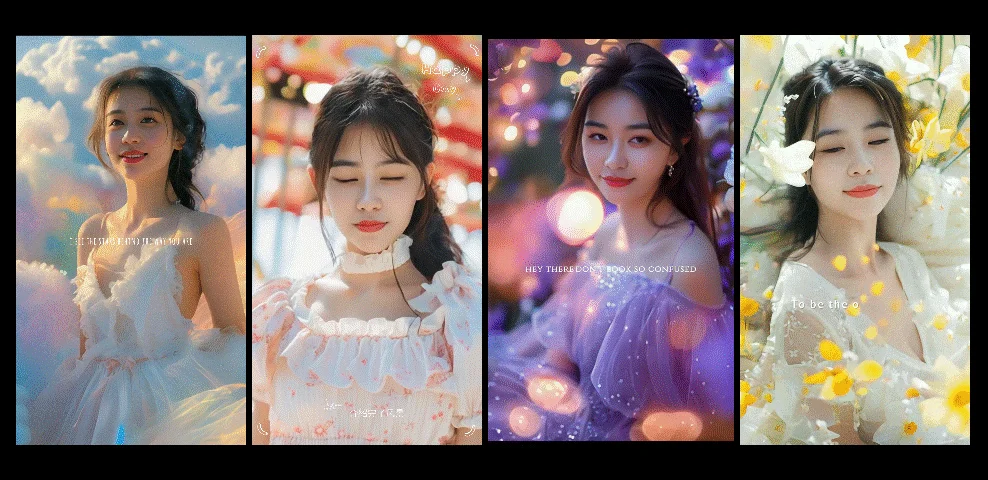
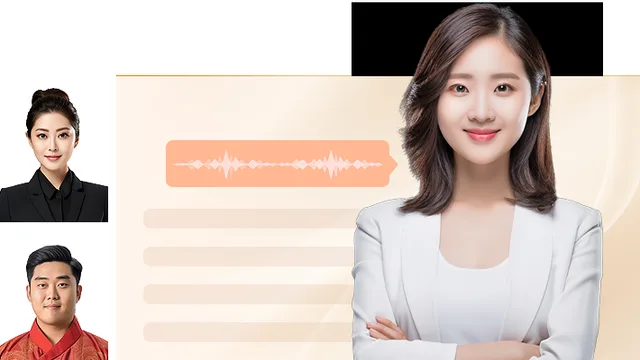
Vimi is SenseTime’s controllable character-video generation model. Its official product page describes using a character image with movement video, animation parameters, speech, or text to guide a performance. Controls cover facial expression and body movement, while the generated scene can also account for hair, clothing, background, and lighting changes around the character.
Where it fits
Choose a character image and a reference that clearly expresses the intended performance. Generate a representative segment, then inspect expression, body movement, and surrounding scene details before developing additional actions or a longer sequence.
Before you commit
The official page describes a model offering; confirm the available access route and input requirements before planning a project.
Sources & editorial notes
This profile summarizes public product information and adds workflow guidance. It is not a hands-on performance review. Check the official website for current prices, limits, and availability.
Source check:
Keep exploring



Create animated short videos from text, pictures, and presentations.

Develop controllable 3D scenes and combine them with AI-generated media.